
An AI MVP is the smallest version of a product where AI does the core job, built to prove one thing: that the model's output is good enough, often enough, that real users will rely on it. It is not a demo, and it is not a full product with an AI feature bolted on. Getting the scope right is most of the work.
Most AI MVPs that fail don't fail because the model was weak. They fail because the team built the wrong 80% around it: a full dashboard, five integrations and a settings page, with no way to tell whether the AI was right. This guide covers what an AI MVP is, what belongs in the first version, what to leave out, and how to know it worked.
What "MVP" means when AI is involved
A classic MVP tests demand: will people sign up, use it and pay? An AI MVP has to test demand and one extra question: does the AI do the job well enough to trust?
That second question changes the build. In a normal app a button either works or it doesn't. An AI feature works most of the time, and the gap between "most" and "enough" decides whether you have a product. So an AI MVP needs ways to measure quality from day one, not after launch.
A useful way to say it: an AI MVP is a narrow product, for one user, doing one job, with the AI's quality measured on real inputs.
What belongs in an AI MVP
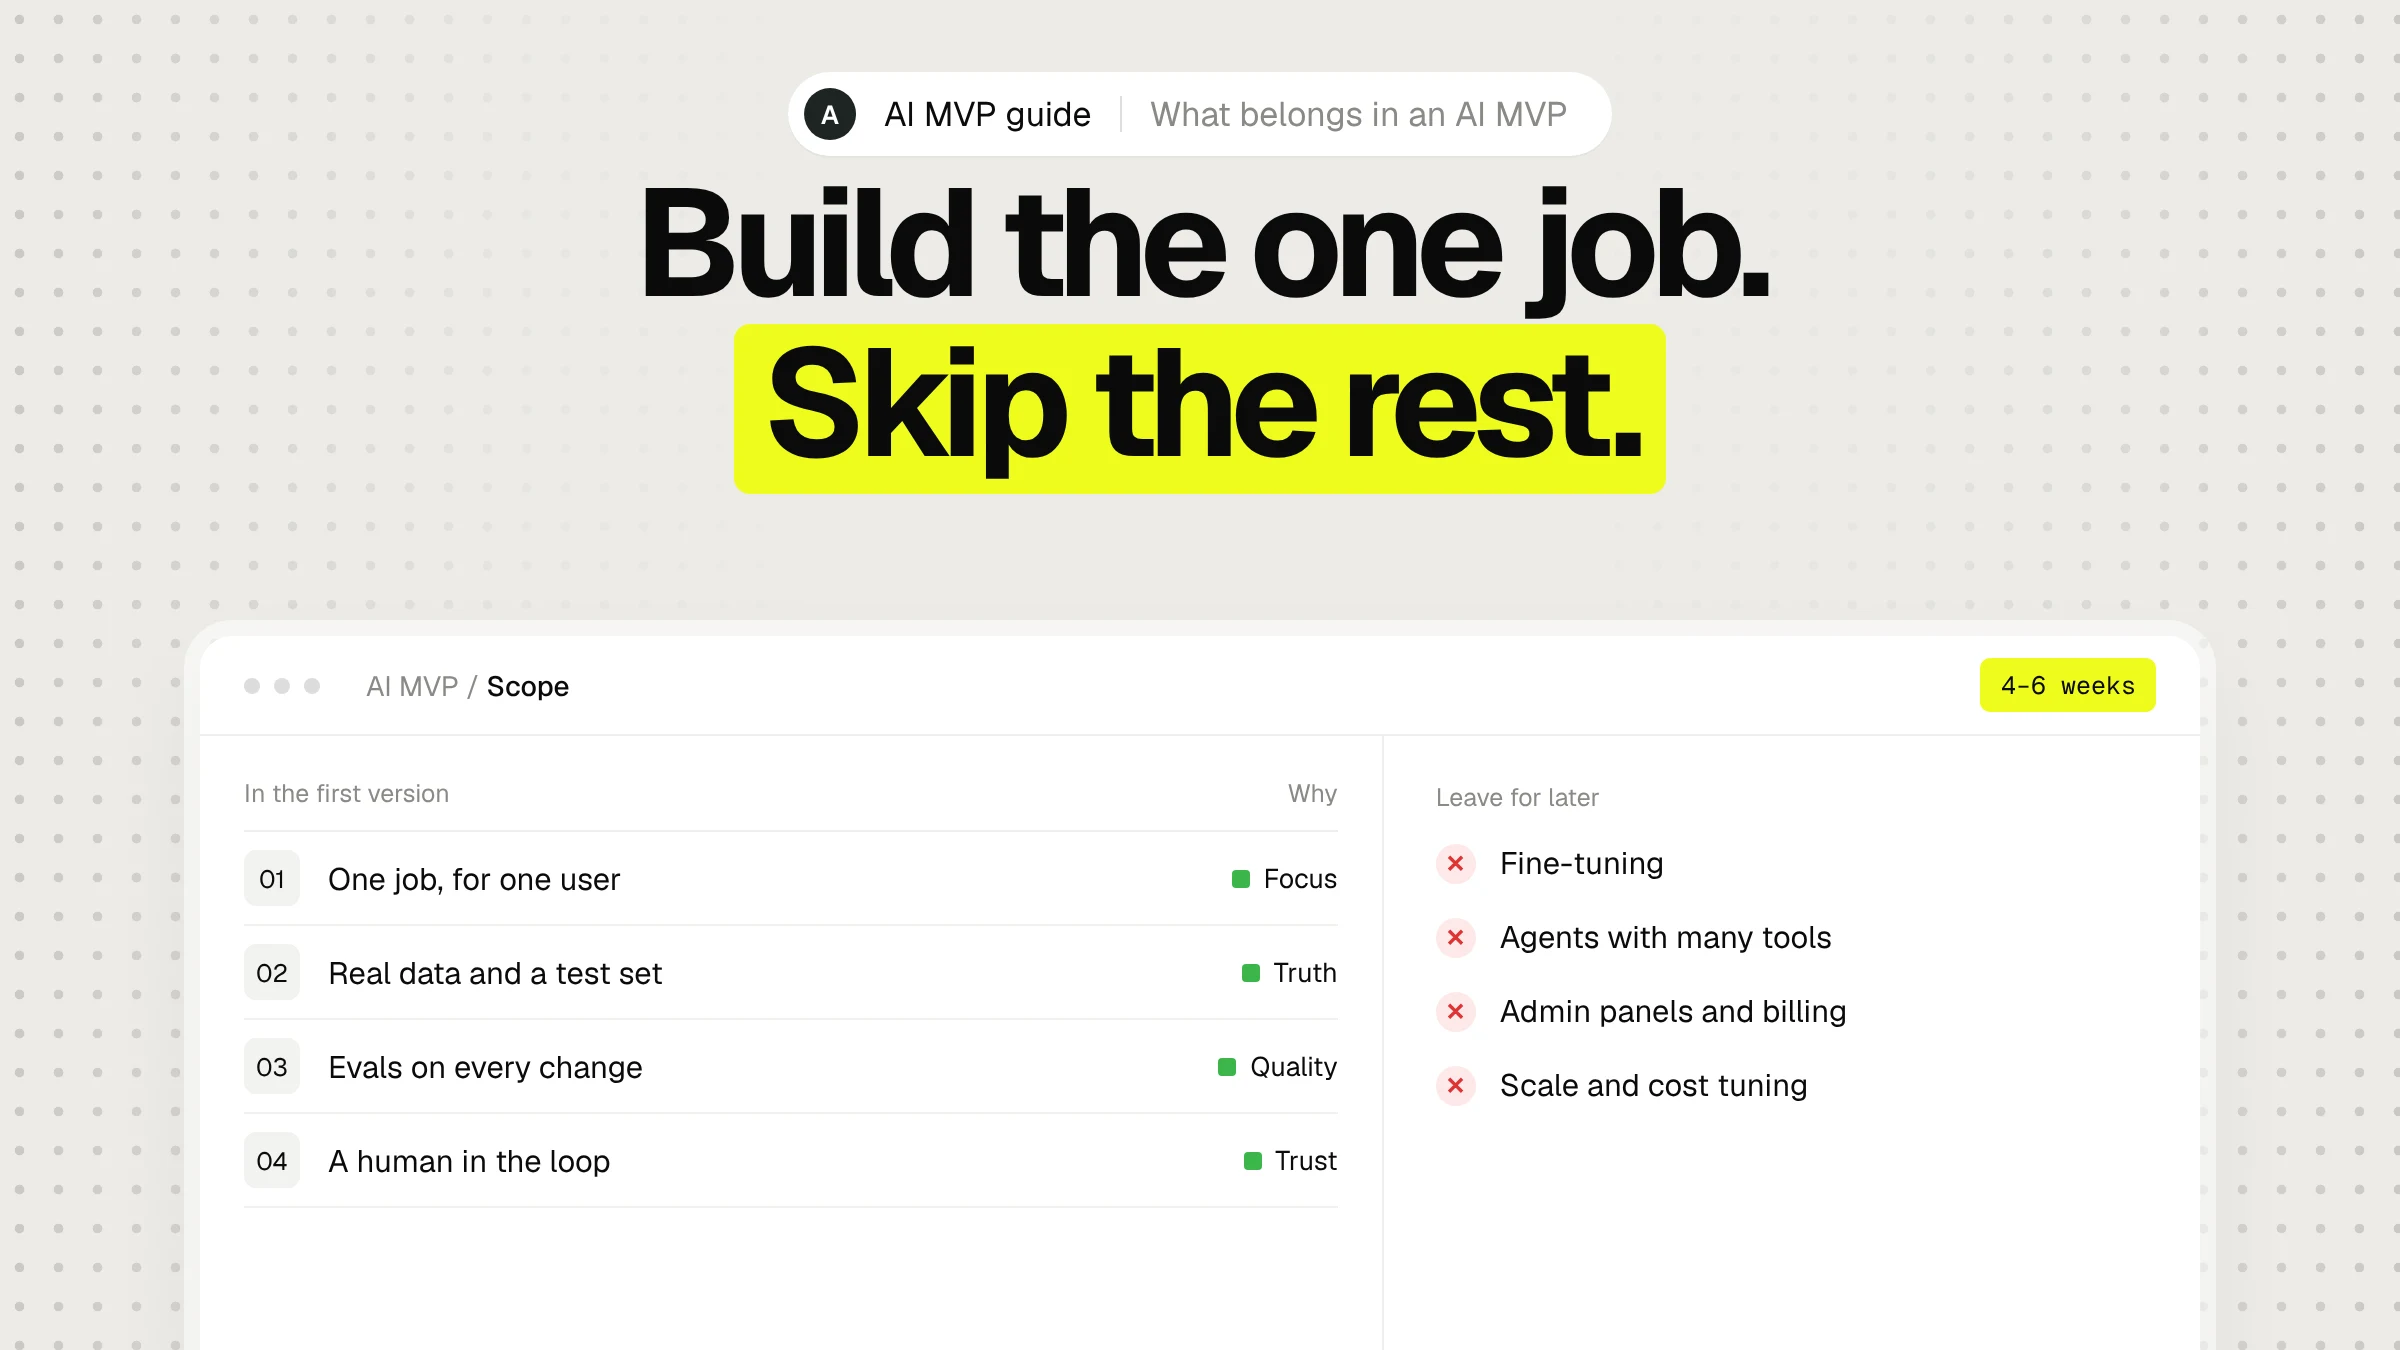
1. One job, for one user
Pick the single task the AI has to get right, and the person who has that task. "AI for lawyers" is a market. "Draft a first reply to a new client inquiry, for a solo immigration lawyer" is an MVP.
If you can't describe the job in one sentence with a clear input and a clear output, the scope is still too wide.
2. A real data path
The AI needs the inputs it will see in production, not tidy samples. That means the actual documents, messages, images or records your users have, with all their mess.
Before building anything, collect 30 to 100 real examples and write down what a good output looks like for each. This set becomes your test set, and it is the most valuable thing you will make in the first two weeks.
3. The simplest model setup that could work
Start with a strong hosted model and a good prompt. Add retrieval (RAG) only when the model needs facts it doesn't have, such as your users' documents or your own product data. Leave fine-tuning for later, when you have enough examples and a clear reason. We go through that decision in fine-tuning vs RAG vs prompt engineering.
The goal at this stage is to learn whether the job can be done, not to optimize cost or latency.
4. Evals: a way to tell if the AI is right
This is the part teams skip, and the part that matters most. An eval is a repeatable check of the AI's output against your test set. It can be simple:
- Exact checks for structured output: did it return valid JSON, the right category, a date in the right format?
- Rubric checks for open text: does the reply mention the right policy, avoid made-up facts, stay under 150 words?
- Human review of a sample every week, scored on the same rubric.
Without evals, every prompt change is a guess. With them, you can see quality go up or down with each change and ship with confidence.
5. A human in the loop where mistakes are expensive
If a wrong answer costs money, trust or safety, the first version should let a person review, edit or approve the output before it reaches the end user. Drafts instead of sends. Suggestions instead of actions.
This also gives you your best training data: every human edit shows exactly where the AI fell short.
6. The core interface, and nothing else
The interface only needs to cover the one job: put the input in, see the output, correct it, use it. Sign-in, a basic history and a way to give feedback on each answer usually round it out.
Design still matters here. How the AI's output is shown, how uncertain answers are flagged and how easy it is to fix a mistake decide whether people trust the product at all.
7. Logging and cost tracking
Log every input, output, model version and user correction, and track what each request costs. You will need this to debug odd answers, to grow your test set and to know whether the unit economics can work before you scale.
What to leave out of the first version
- Multiple models and fallbacks. One good model is enough to learn from.
- Fine-tuning. It needs data you don't have yet.
- Agents with many tools. Each extra tool multiplies the ways things go wrong. Start with one step, then chain.
- Lots of integrations. One input source and one output destination. Import by upload or copy-paste is fine at first.
- Admin panels, roles and billing systems. A spreadsheet and a payment link can carry the first users.
- Scale work. Caching, queues and cost tuning come after you know the output is good.
A realistic AI MVP timeline
For a focused scope with a senior team, four to six weeks is a common range:
- Weeks 1 to 2: collect real examples, write the test set and the quality bar, get a prompt baseline working, and spike the riskiest integration.
- Weeks 3 to 4: build the core flow and the review step, wire up logging, and run evals on every change.
- Weeks 5 to 6: fix the failure cases the evals found, harden the edges, and put it in front of the first real users.
Some products go faster. We built Rendervi, an AI render studio for architects, from zero to first revenue in three weeks, because the job was narrow and the quality was easy to judge by eye. Products with messy data or high stakes take longer, and that is fine as long as you are measuring.
How to know the AI MVP worked
Decide this before you build. A good AI MVP ends with clear answers to three questions:
- Quality: on real inputs, how often is the output good enough to use as-is, good enough after a quick edit, or wrong? Set the bar up front, for example "usable as-is or after one edit in 8 of 10 cases".
- Usage: do the target users come back and use it for the real job, without being reminded?
- Economics: does the cost per task leave room for a price people will pay?
If all three are yes, you have earned the right to scale. If quality is the problem, you have a test set and logs that show exactly where to work next.
Building your AI MVP
If you want a team that has done this before, our AI MVP development work covers the whole path: scoping the one job, building the data path and evals, designing the interface and shipping it to real users. It runs on a subscription from $1,690 a month with a 3-day free trial, so you can start small and stop when the MVP has answered its questions. See pricing, or read how to choose an AI development agency if you are still comparing options.
For a deeper look at scoping, building and shipping, read our guide to AI MVP development.